Execution
Make state and failures observable.
AI Agent Infrastructure Engineer · Nigeria
I build the systems AI agents run on.
Agent harnesses, persistent runtimes, memory, and evaluation infrastructure. I focus on how agents execute, recover, and produce work that can be checked.
Flow ResearchWorkstream Lead
Snorkel AIExpert Contributor & Reviewer
Open sourceHarness · Runtime · Memory
AGENT INFRASTRUCTUREMY FOCUS
01
HARNESSGive agents a working environment.
02Tools, context, workspaces, and coordination.
RUNTIMEKeep execution dependable.
03Supervision, persistent state, and recovery.
MEMORYCarry useful context forward.
04Retention, retrieval, and isolation.
EVALUATION & GOVERNANCEMake the work verifiable.
Requirements, authority, and evidence.
Execution, recovery, and evaluation are engineering responsibilities.
AGENT RUNTIMES◆DURABLE MEMORY◆POLICY ENFORCEMENT◆LONG-HORIZON EVALUATION◆IMMUTABLE EVIDENCE◆HUMAN + AGENT WORK
01 Selected open-source systems
Harness. Runtime.
Memory. Evaluation.
These projects cover the parts of agent infrastructure I build: execution, supervision, memory, and governed work. Each repository documents its own scope and implementation.
01 / Agent harnessOpen source
OmniCoreAgent
A Python agent harness that owns the execution loop: parallel tool calls, structured observations, context management, workspaces, and subagents. Includes durable background tasks, execution traces, and REST/SSE APIs.
Tool execution · Context control · Agent APIs
02 / Agent runtimeOpen source
OmniDaemon
An event-driven runtime that runs agents as supervised processes. Handles health monitoring, recovery, retries, dead-letter queues, and distributed coordination independently of the agent framework.
Process supervision · Recovery · Coordination
03 / Agent memoryOpen source
OmniMemory
A memory framework for retaining and retrieving useful context across interactions. Combines memory synthesis, conflict resolution, retrieval scoring, and isolation across applications, users, and sessions.
Persistent context · Retrieval · Isolation
04 / Governed work & evaluationOpen source · v0.1 in development
Workstream
Infrastructure for work performed by humans, agents, or both. Project policy governs requirements and acceptance; immutable submissions, checks, and authorized decisions preserve the evidence behind recognized contributions.
Project policy · Immutable evidence · Contribution records
02 Engineering approach
Follow the execution.
Account for failure.
Agent systems need clear answers to practical questions: where does work wait, what happens when a tool fails, which state survives a restart, and who is allowed to take the next action?
I build around those questions. The runtime manages execution and recovery. Permissions bound actions. Evaluation establishes whether the resulting work meets its requirements.
Recovery
Define what survives a retry.
Authority
Check permissions at the boundary.
Evaluation
Tie decisions to inspectable evidence.
03 Selected experience
The work behind
the systems.
My work spans backend infrastructure, agent systems, and evaluation. I bring the same attention to state, concurrency, failure, and evidence across each of these areas.
GOVERNED WORK · BACKEND SYSTEMS · EVALUATION INFRASTRUCTURE
Building the infrastructure behind recognized contributions.
I lead the design and development of Workstream: project policy, identity and authorization, immutable submissions, review and revision lifecycles, and contribution records for human and agent work.
Inside WorkstreamTASK AUTHOR · REVIEWER · FRONTIER MODEL EVALUATION
Designing and reviewing evaluations for coding agents.
I create and review technically rigorous evaluations for advanced AI systems, with a focus on workflows that must remain correct across multiple steps, tools, and execution attempts.
- Create technically rigorous coding and agent-evaluation tasks for terminal-based and long-running execution workflows.
- Validate model behavior against detailed rubrics and specifications, including comparative analysis across repeated execution runs.
- Review tasks created by other contributors for benchmark quality, technical correctness, and alignment with project standards.
ELECTRIC-VEHICLE INFRASTRUCTURE
Building the backend control plane for connected charging stations.
Worked on the end-to-end backend and infrastructure design of OCPP charging-station management systems, balancing real-time protocol communication, concurrent workloads, and operational simplicity.
- Built Python services with Django REST Framework and FastAPI, using WebSockets for OCPP communication and RabbitMQ/Celery for event-driven background work.
- Improved database schemas and queries for transaction-heavy charging workflows.
- Moved internal deployments from Docker Compose to Docker Swarm, enabling rolling updates across project environments.
- Designed GitHub Actions pipelines for automated builds, tests, and containerized deployments.
REAL-TIME PROTOCOL SYSTEMS→DISTRIBUTED EXECUTION→AGENT INFRASTRUCTURE→LONG-HORIZON EVALUATION
04 Current build
FLOW RESEARCH · WORKSTREAM v0.1 · IN DEVELOPMENT
Infrastructure for accountable human and agent work.
I lead Workstream at Flow Research. Project policy defines the requirements and acceptance path for work. The system preserves submissions, check results, and authorized decisions as evidence behind contribution records.
A contribution should be traceable to the work, the rules that applied, and the decision that recognized it.Explore Workstream
EXAMPLE ACCEPTANCE PATHWITH REVIEW
CONTENT IDENTITYsha256:server-computedbyte count + immutable identity
✓SubmittedExact bytes recorded
✓CheckedRequired checks recorded
✓ReviewedDecision bound to version
04AcceptedContribution created
The project policy determines the required checks and review.
05 Agent systems evaluation
Evaluate the work
across the whole run.
Long-horizon agents fail in ways a single final answer cannot reveal. My research focuses on benchmark infrastructure that evaluates the entire trajectory: environment, action, artifact, evidence, and acceptance.
Task validity
Can the task actually be solved from the supplied evidence, pinned environment, and stated contract?
Evaluator integrity
Do the checks verify the real work, or only a self-consistent output that an agent can fabricate?
Long-horizon evidence
Can every consequential decision be traced across attempts, tools, artifacts, reviews, and revisions?
Reproducible acceptance
Would the same exact bytes, policy version, and environment justify the result again later?
EVALUATION FOUNDATIONSREPRODUCIBLE ENVIRONMENTSVALID CHECKSTRACEABLE EVIDENCE
06 Earlier work & research
01
GOOGLE GEMINI CHALLENGE · JAN 2026
Policy-controlled
agent payments.
OmniAgentPay was the early implementation. It won the Google Gemini Challenge at the Agentic Commerce on Arc Hackathon. The work then evolved into OmniClaw: a buyer-side policy-controlled core and a separate hosted x402 facilitator for seller settlement.
1STPLACE
Policy-Constrained Financial Execution for Autonomous Agents
A formal architecture for separating an agent's ability to request payment from the authority to move money through policy, evidence, and bounded execution.
DOI10.5281/zenodo.20487323
Read the paper 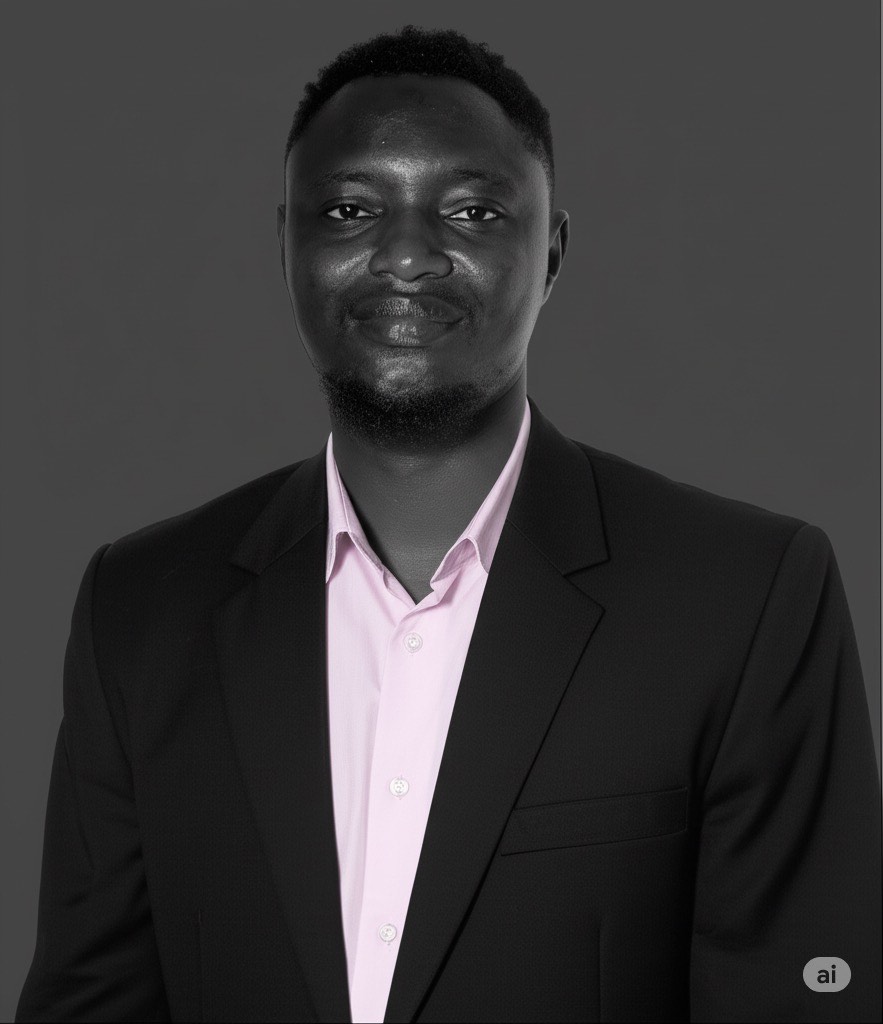
ABIOLA ADESHINANIGERIA
07 The engineer behind the systems
I build around
the agent.
I'm Abiola Adeshina, an AI agent infrastructure engineer based in Nigeria. I build agent harnesses, runtimes, orchestration, memory, and evaluation systems. My foundation is backend and distributed systems engineering.
At Snorkel AI, I create and review technically rigorous evaluations for frontier coding agents and advanced AI systems, focusing on solvability, reproducibility, coverage, grader robustness, and resistance to shortcuts. The same systems discipline I developed in real-time EV infrastructure now shapes how I evaluate long-horizon agent behavior.
At Flow Research, I lead Workstream, building infrastructure for governed human and agent work. Across these projects, I care about what survives a failure, how authority is enforced, and whether the evidence supports the result.
CORE DISCIPLINEDistributed systemsRuntimes, orchestration, reliability
SPECIALIZATIONAgent infrastructureHarnesses, memory, and evaluation
EARLIER SYSTEMSEV chargingOCPP charging-station management systems
BUILDER ROLEFounderomnirexflora-labs
Agent infrastructure & evaluation
Building systems
agents depend on?
I'm interested in engineering roles and collaborations around agent runtimes, orchestration, evaluation platforms, and reliable execution. Let's talk about what you're building.
Email Abiola